AI Foundations
Ball don't lie, and neither does linear algebra.
In the future, AI will be the last problem humans solve by themselves. This final frontier is called AGI: Artificial General Intelligence. It will do just about everything a human can, and if it can't do it it will learn it.
As humans we learn in the brain and evolve through evolution. Machines learn in the cloud and evolve in the cloud, on processors with 80 billion transistors apiece, fed by datacenters that draw the power of a small city, programmed to do nothing but learn and evolve.
After they are born, nothing will be the same. Every problem we've been trying to solve, from medicine for every disease to a unified theory of physics, will be solved. Just not by us.
But that's AI of the future. Today, AI is seeping its tentacles into just about everything. It's taken over the voice assistants of the past, and turbocharged our code completion engines. What used to be ML is now AI, in part due to the generative wave: chatbots that hold a real conversation, image models that paint on demand, code completion that finishes your sentences before you do.
Today, I'll talk about what AI is, in concrete terms.
What Is AI
Three definitions, that you will certainly come across in most textbooks:
"The field of study that gives computers the ability to learn without being explicitly programmed."
— Arthur Samuel, 1959, coined while building a checkers program at IBM. The most-quoted definition in every textbook.
"A computer program is said to learn from experience E with respect to some class of tasks T and performance measure P, if its performance at tasks in T, as measured by P, improves with experience E."
— Tom Mitchell, 1997, from Machine Learning (McGraw-Hill). The formal definition.
"Artificial intelligence is the science and engineering of making intelligent machines, especially intelligent computer programs."
— John McCarthy, 1956, who coined the term "artificial intelligence" at the Dartmouth Workshop.
In short, AI is giving intelligence without explicit programming. It started with symbolic AI: logic, rules, search, puzzles. These developed into expert systems, using hard-coded rules for medicine, engineering, finance.
The early confident promises ran out, twice. The 1974-1980 AI winter. The 1987-1993 winter followed the collapse of the LISP-machine industry and expert systems' failure to scale into the enterprise. Funding evaporated both times. The current boom is the longest sustained period of progress AI has ever had, which is either a sign that the technology finally works or a sign that the third winter will be uglier than the first two when it comes.
Game-playing AI was the comeback story between the winters and the modern era. IBM's Deep Blue beat Garry Kasparov at chess in 1997 with brute-force search and a hand-crafted evaluation function. IBM's Watson took Jeopardy! in 2011 with statistical NLP layered over a curated knowledge base. DeepMind's AlphaGo beat Lee Sedol at Go in 2016, combining deep neural networks with Monte Carlo tree search in a game whose branching factor had been considered intractable. AlphaZero learned chess, shogi, and Go from self-play in a matter of hours the next year.
The modern era starts around 2012, when AlexNet won ImageNet with a deep convolutional network and a pair of GPUs, dropping the image-classification error rate by ten points and making deep learning the default. Word2vec (2013) showed that words could live as vectors in a learned space. The Transformer paper (2017) replaced recurrence with attention. GPT-3 (2020) showed that scale alone, billions of parameters and trillions of tokens, was a research direction. By late 2022 a public-facing chatbot crossed 100 million users in two months, and the industry has not stopped pouring concrete since.
Mathematically, an AI is nothing more than a function fitting by optimization. Simpler AIs can learn linear relationships and need just a few linear algebra equations at their disposal. More complex ones, such as language models, employ advanced techniques like neural networks, loosely modeled on the brain's layered neurons. As they are more sophisticated, they too need more sophisticated mathematics: calculus, statistics, and information theory. You don't need advanced maths to train or deploy AI models, but to make advancements in frontier AI you certainly will. You won't understand backpropagation if you don't understand derivatives and the chain rule; and thankfully, that's not our goal today.
The goal here is to use AI to solve day-to-day problems, not derive new theorems for the future. At least, not yet.
In Concrete Terms
The goal is to train an AI model, which is nothing more than the learned function mapping training data to predictions. Your training data contains the features you wish to train on, the input variable (i.e., square footage when predicting house price). The thing you're predicting is called the label or target (i.e., the actual house price).
Parameters are the internal values the model learns, such as the famous weights that correspond to how large language models store their knowledge. Along the way, you'll optimize hyperparameters, which are essentially settings you choose before training (i.e., learning rate, batch size, regularization strength). The learned function improves via a loss function, which measures how wrong the model is. For example, if you have a set of features you wish to train on and the labels that you know to be ground truth, you can simply minimize for the mean-squared error:
$$ \mathrm{MSE} = \frac{1}{n} \sum_{i=1}^{n} \left( y_i - \hat{y}_i \right)^2 $$
The dataset is usually broken into a:
- Training Set Data the model learns from, usually 70–80% of your data.
- Validation Set Held-out data for tuning hyperparameters.
- Test Set Final unseen data for honest performance evaluation.
The split exists because of overfitting: the failure mode where a model memorizes training data instead of learning the pattern. A model that scores 99% on training and 60% on test isn't smart; it's a lookup table. Generalization is the opposite, where the model performs about as well on data it's never seen as on data it has. Holding out a test set is the only way to know which one you've got.
Underfitting is overfitting's mirror twin: the model is too simple, misses real patterns, and is wrong on both training and test. The bias-variance tradeoff is the search for the sweet spot: a model complex enough to capture the signal, simple enough not to memorize the noise. Most hyperparameter tuning is, in effect, walking that line.
After your model is trained, you make predictions via inference.
Metrics answer the question "did it work?" For classification, the headline is accuracy (fraction correct), but accuracy lies when classes are imbalanced. Precision is the fraction of positive predictions that were right; recall is the fraction of actual positives the model caught. F1 is their harmonic mean. For regression, MSE or RMSE is the default; MAE when outliers shouldn't dominate.
Basketball IQ
In most academic AI introductory texts, a problem would be built upon:
- Iris dataset 150 flowers, four features, three species
- MNIST 70,000 handwritten digit images, ten classes
- California / Boston housing geographic and structural features, sale price
But, I find these to be too academic. My closest relation to Iris is that it's my grandmother's name. So I would like to step through a problem relevant to today. Literally today. Like, the NBA finals.
I like the fact that this problem is simple and easily relatable. But it's actually not an ideal AI problem. While it seems like a lot of data, an entire NBA season and playoffs, it really boils down to 82 regular season games per team and roughly 80 playoff games league-wide. Not ideal. But it'll be fun to watch our prediction play out in real time.
The full system, code, and whitepaper live at github.com/illyastarikov/artificial. Briefly: the model is a four-head ensemble (Elo + logistic regression + two LightGBMs), the features are 55 per-game columns, the label is whether the home team wins, and the dataset is 21,742 games split chronologically. The detailed model description, the metrics on the test set, and the live 2026 predictions are in the NBA Finals section below.
You don't have to figure out what regression or what sort of problem this is yet, we're going to do that in the next section.
Learning Paradigms
AI doesn't learn one way. There are four broad paradigms, ordered below from most-deployed in industry to most-research-flavored. Real systems mix and match, but every approach falls into one of these buckets.
Supervised learning
You have inputs and the correct outputs. The model learns the mapping. The dominant paradigm in industry.
Classification Predict a discrete category.
- Algorithms: logistic regression, SVMs, random forests, gradient boosting, k-NN, naive Bayes, neural nets.
- Famous uses: Gmail spam filtering, breast cancer detection from mammograms, ImageNet (AlexNet, 2012), credit card fraud detection.
Regression Predict a continuous number.
- Algorithms: linear/ridge/lasso regression, regression trees, gradient boosting (XGBoost), neural nets.
- Famous uses: Zillow's Zestimate (home prices), Uber surge pricing, demand forecasting at Walmart.
Unsupervised learning
No labels, no ground truth. The model has to find structure on its own: groups of similar things, hidden axes of variation, outliers that don't fit any pattern. Less common than supervised learning in deployed products, but it's how you make sense of data you've never seen before.
Clustering - Algorithms: k-means, DBSCAN, hierarchical, Gaussian mixtures. - Famous uses: customer segmentation, news topic grouping (Google News), gene expression analysis.
Dimensionality reduction - Algorithms: PCA, t-SNE, UMAP, autoencoders. - Famous uses: visualizing high-dim data, image compression, eigenfaces (face recognition, 1991).
Anomaly detection - Algorithms: isolation forest, one-class SVM, autoencoders. - Famous uses: fraud detection, network intrusion, manufacturing defect detection.
Association rules - Algorithms: Apriori, FP-growth. - Famous uses: Amazon "frequently bought together", market-basket analysis.
Semi-supervised & self-supervised learning
Mostly unlabeled data with a sprinkle of labels (semi-), or labels invented from the data itself like "predict the next word" (self-).
- Famous uses: Google's early image search labeling, word2vec (2013), and the entire pre-training era of modern AI.
Reinforcement learning
An agent takes actions in an environment and learns from rewards. No labeled examples; feedback comes from outcomes.
- Algorithms: Q-learning, SARSA, policy gradients, actor-critic, DQN, PPO.
- Famous uses: AlphaGo beating Lee Sedol (2016), AlphaZero, OpenAI Five (Dota 2), DeepMind's Atari agents, robot locomotion, data-center cooling at Google.
Tip-Off
Enough theory. The NBA Finals problem is supervised at heart: every past game has a known winner, every feature has a known value, the model learns the mapping. The next section runs it.
NBA Finals
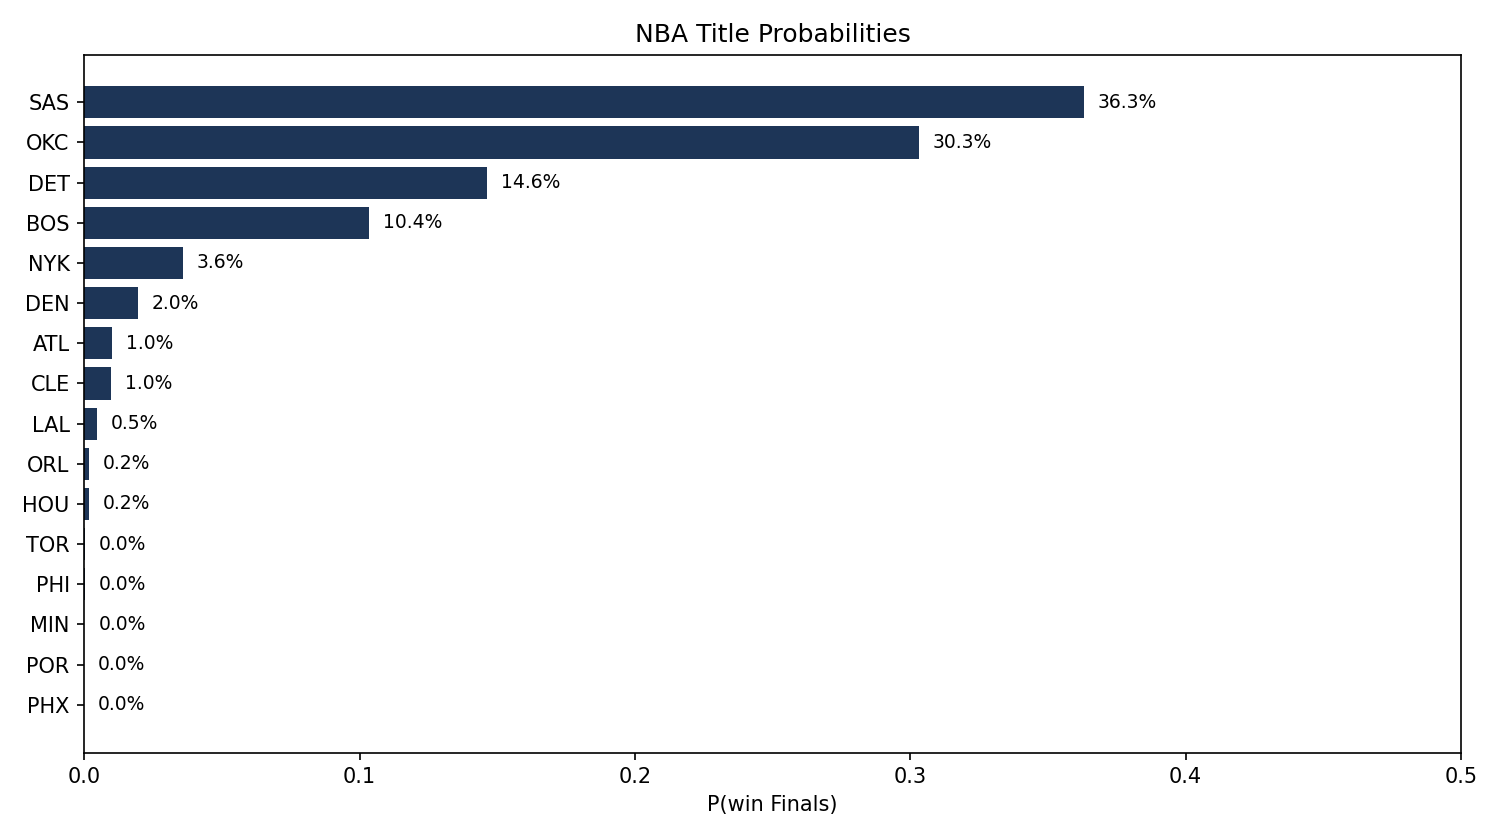
This bracket is the model's call from the start of the 2026 playoffs, before a single game tipped. The sections below walk through the model behind it, how accurate it is on held-out games, the bracket it produced, and where it has already gone wrong. How It Played Out grades the call against the real postseason.
The Model
Four predictors look at the same game from different angles: a chess-style team rating, a straight-line classifier, a tree ensemble that picks the winner, and another tree ensemble that picks the scoring margin. Their four predictions get blended together and run through a calibration step so the stated confidence matches the real hit rate. The full math, the hyperparameters, and the code are in the whitepaper.
Results on the Test Set
Across 60 independent training seeds on 3,261 held-out games:
| Metric | Mean | Std |
|---|---|---|
| Log-loss | 0.634 | 0.016 |
| Brier score | 0.215 | 0.004 |
| Accuracy | 65.9% | 0.8% |
| Expected calibration error | 0.023 | 0.006 |
65.9% accuracy beats the all-time NBA home-win rate (~60%) and lands within about a point of the ~67% that strong public game-prediction models have historically hit calling winners straight up. An ECE of 2.3% means when the model says "65% chance of winning," teams in that bucket win about 65% of the time. The calibration is honest.
The Start-of-Playoff Bracket
Before the first game, with all sixteen teams alive, a vectorized Monte Carlo simulator runs 100,000 best-of-seven bracket trials respecting the 2-2-1-1-1 home schedule, each game drawn from the model's per-game probabilities. A full bracket sim takes 30 seconds. The top four teams by title odds:
| Team | P(Conf. Finals) | P(Finals) | P(Champion) |
|---|---|---|---|
| SAS | 80.4% | 48.2% | 36.3% |
| OKC | 86.8% | 44.7% | 30.3% |
| DET | 69.7% | 41.9% | 14.6% |
| BOS | 54.3% | 29.9% | 10.4% |
By title odds, SAS leads at 36% — a 2-seed the model rates like a 1-seed, in a sim where 2-seeds collectively win it all more often than 1-seeds do (47% to 45%). OKC is a close second. The East trails badly: DET and BOS fill out the top four, while the two teams that would actually emerge from it — NYK and CLE — sit way down at 3.6% and 1.0%. Hold that thought.
Where the Model Missed
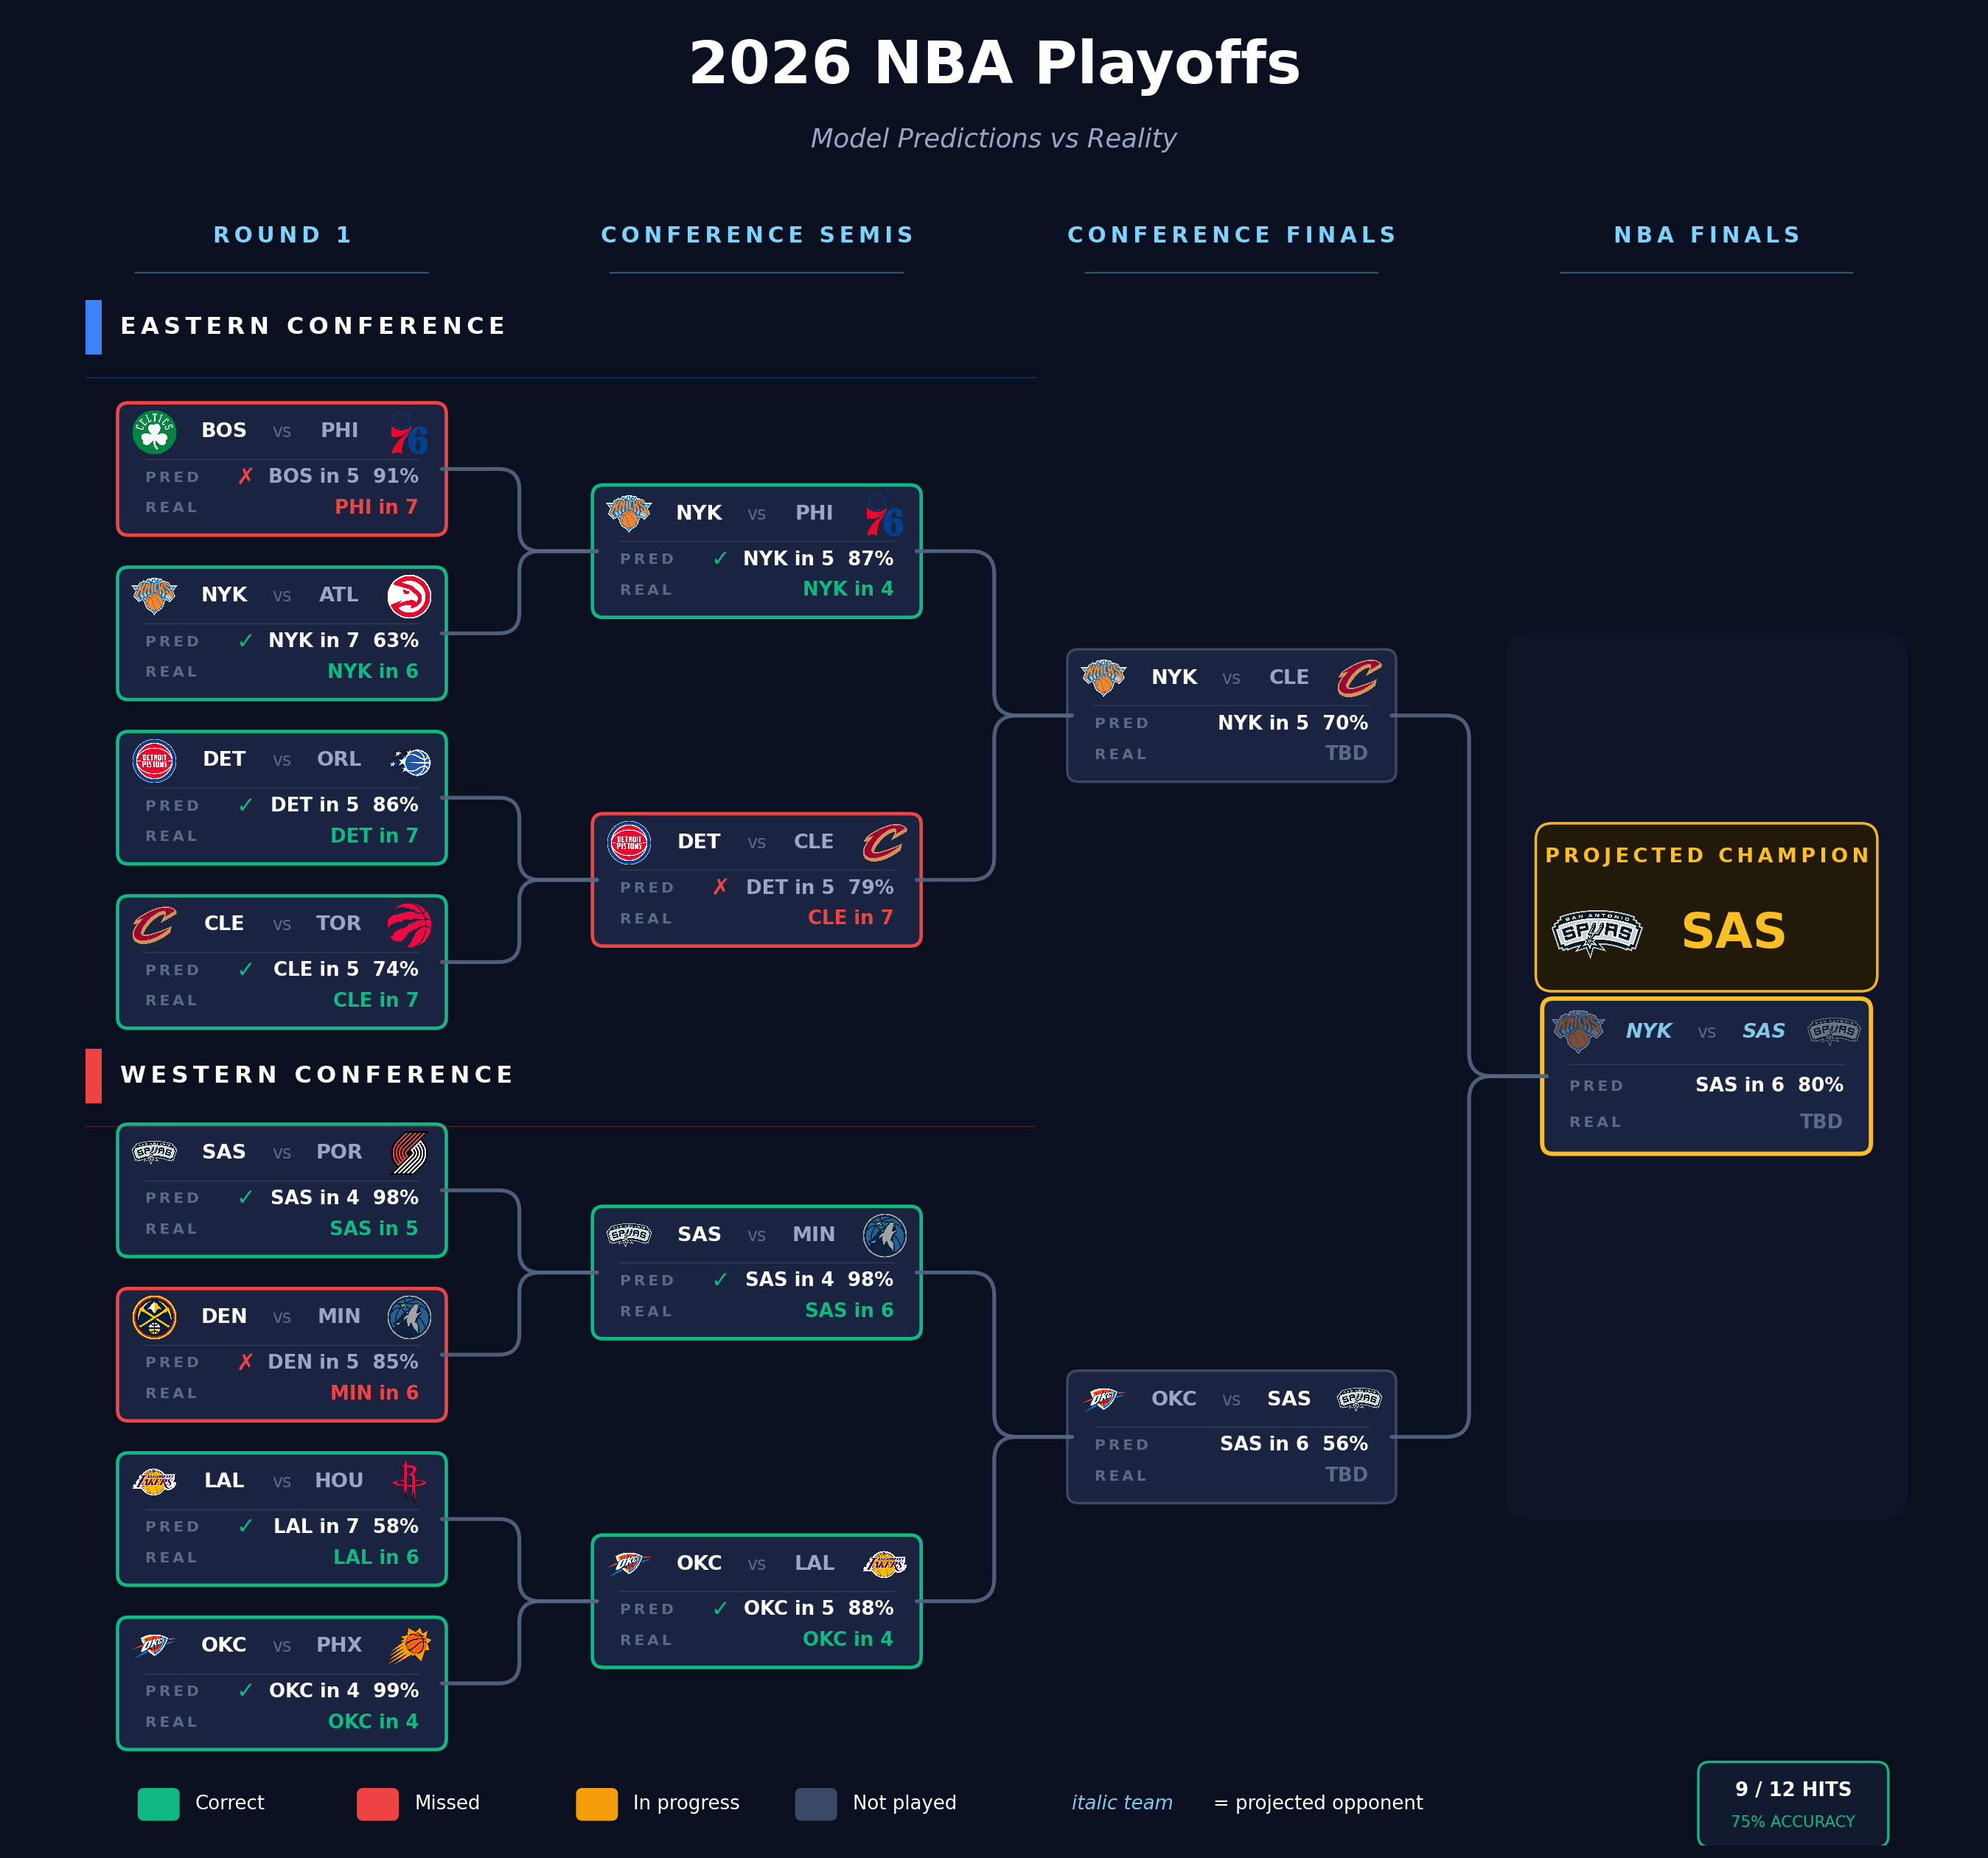
3 of the 12 series completed in the first two rounds:
- PHI over BOS, Round 1, 3-1 comeback. Boston led 3-1; Philadelphia won the next three to take the series 4-3, the 14th team in NBA history to erase a 3-1 deficit. The model gave BOS 91% to advance.
- MIN over DEN, Round 1. A 6-seed beating a 3-seed. The model gave DEN 85%.
- CLE over DET, Round 2, Game 7. Detroit had the higher seed and the pre-series Elo edge; the model gave DET 79%. Cleveland won 4-3.
All three were calls the books also missed. No model nails every series; the question is whether it's biased. ECE of 2.3% says no.
Scenarios
Each of the 100,000 Monte Carlo trials is itself a complete bracket realization. Aggregate them and you get the title odds above. Look at individual trials and you get a distribution of brackets, some of which are pure chalk, a few of which are total chaos.
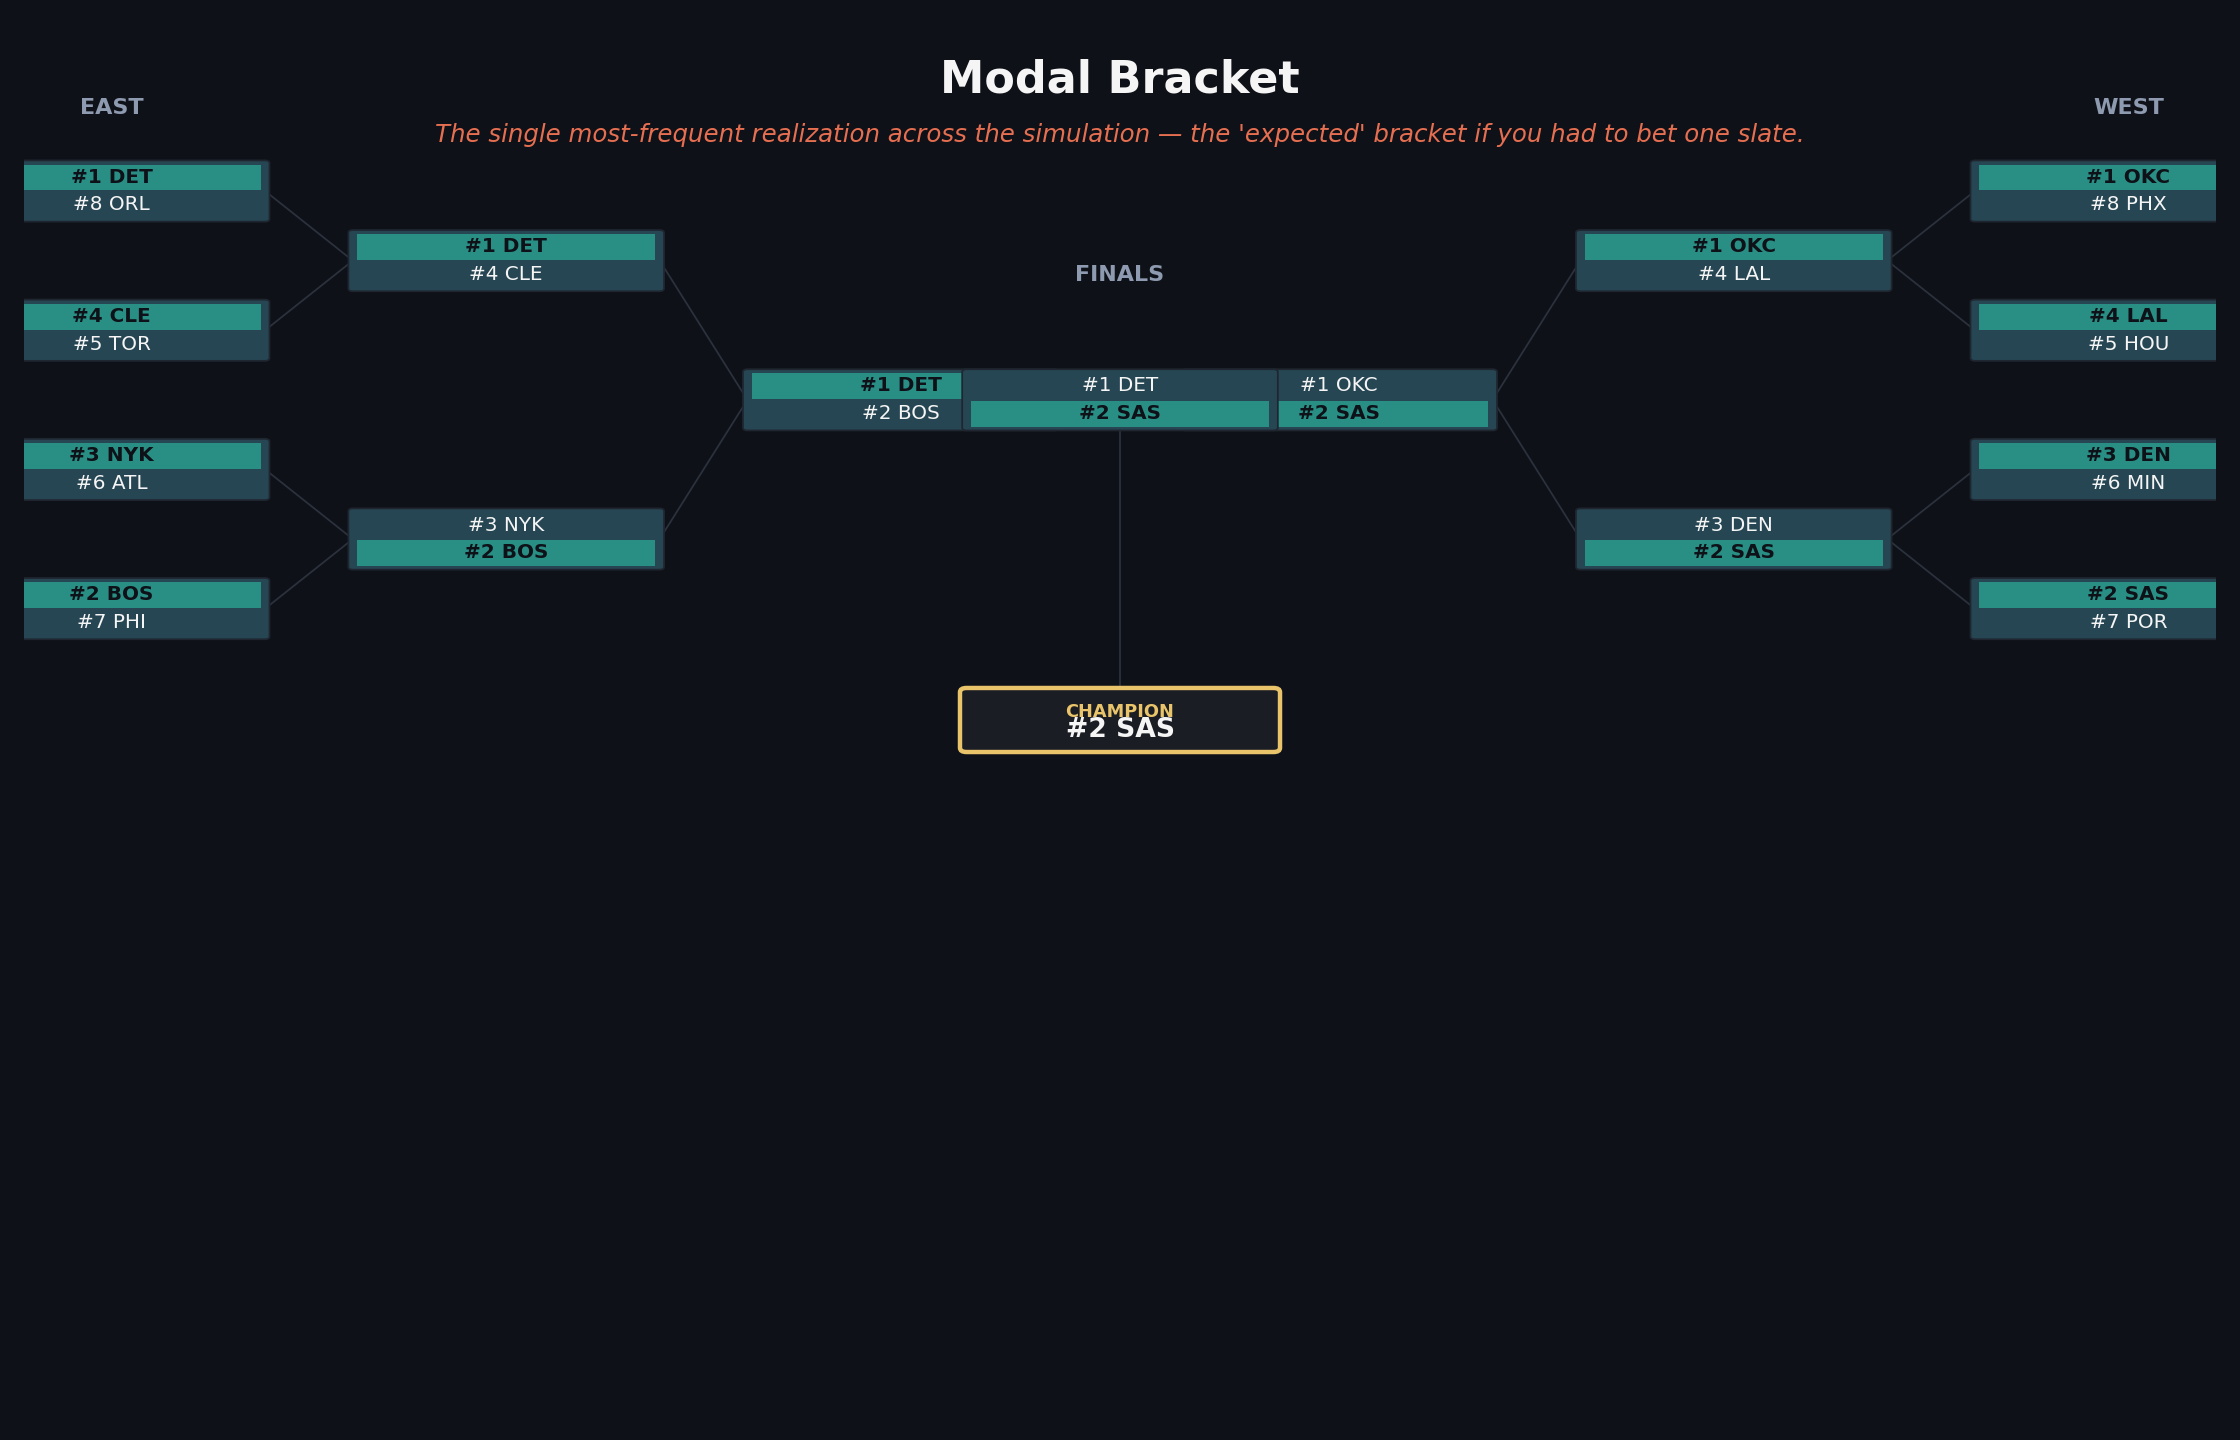
The most-frequent realization across the 100k trials is SAS over DET — the same SAS that tops the title odds. The model's single best bracket and its overall favorite agree on the champion. (Pure chalk, every top seed advancing, would crown OKC; the model likes SAS enough to override the seed line.)
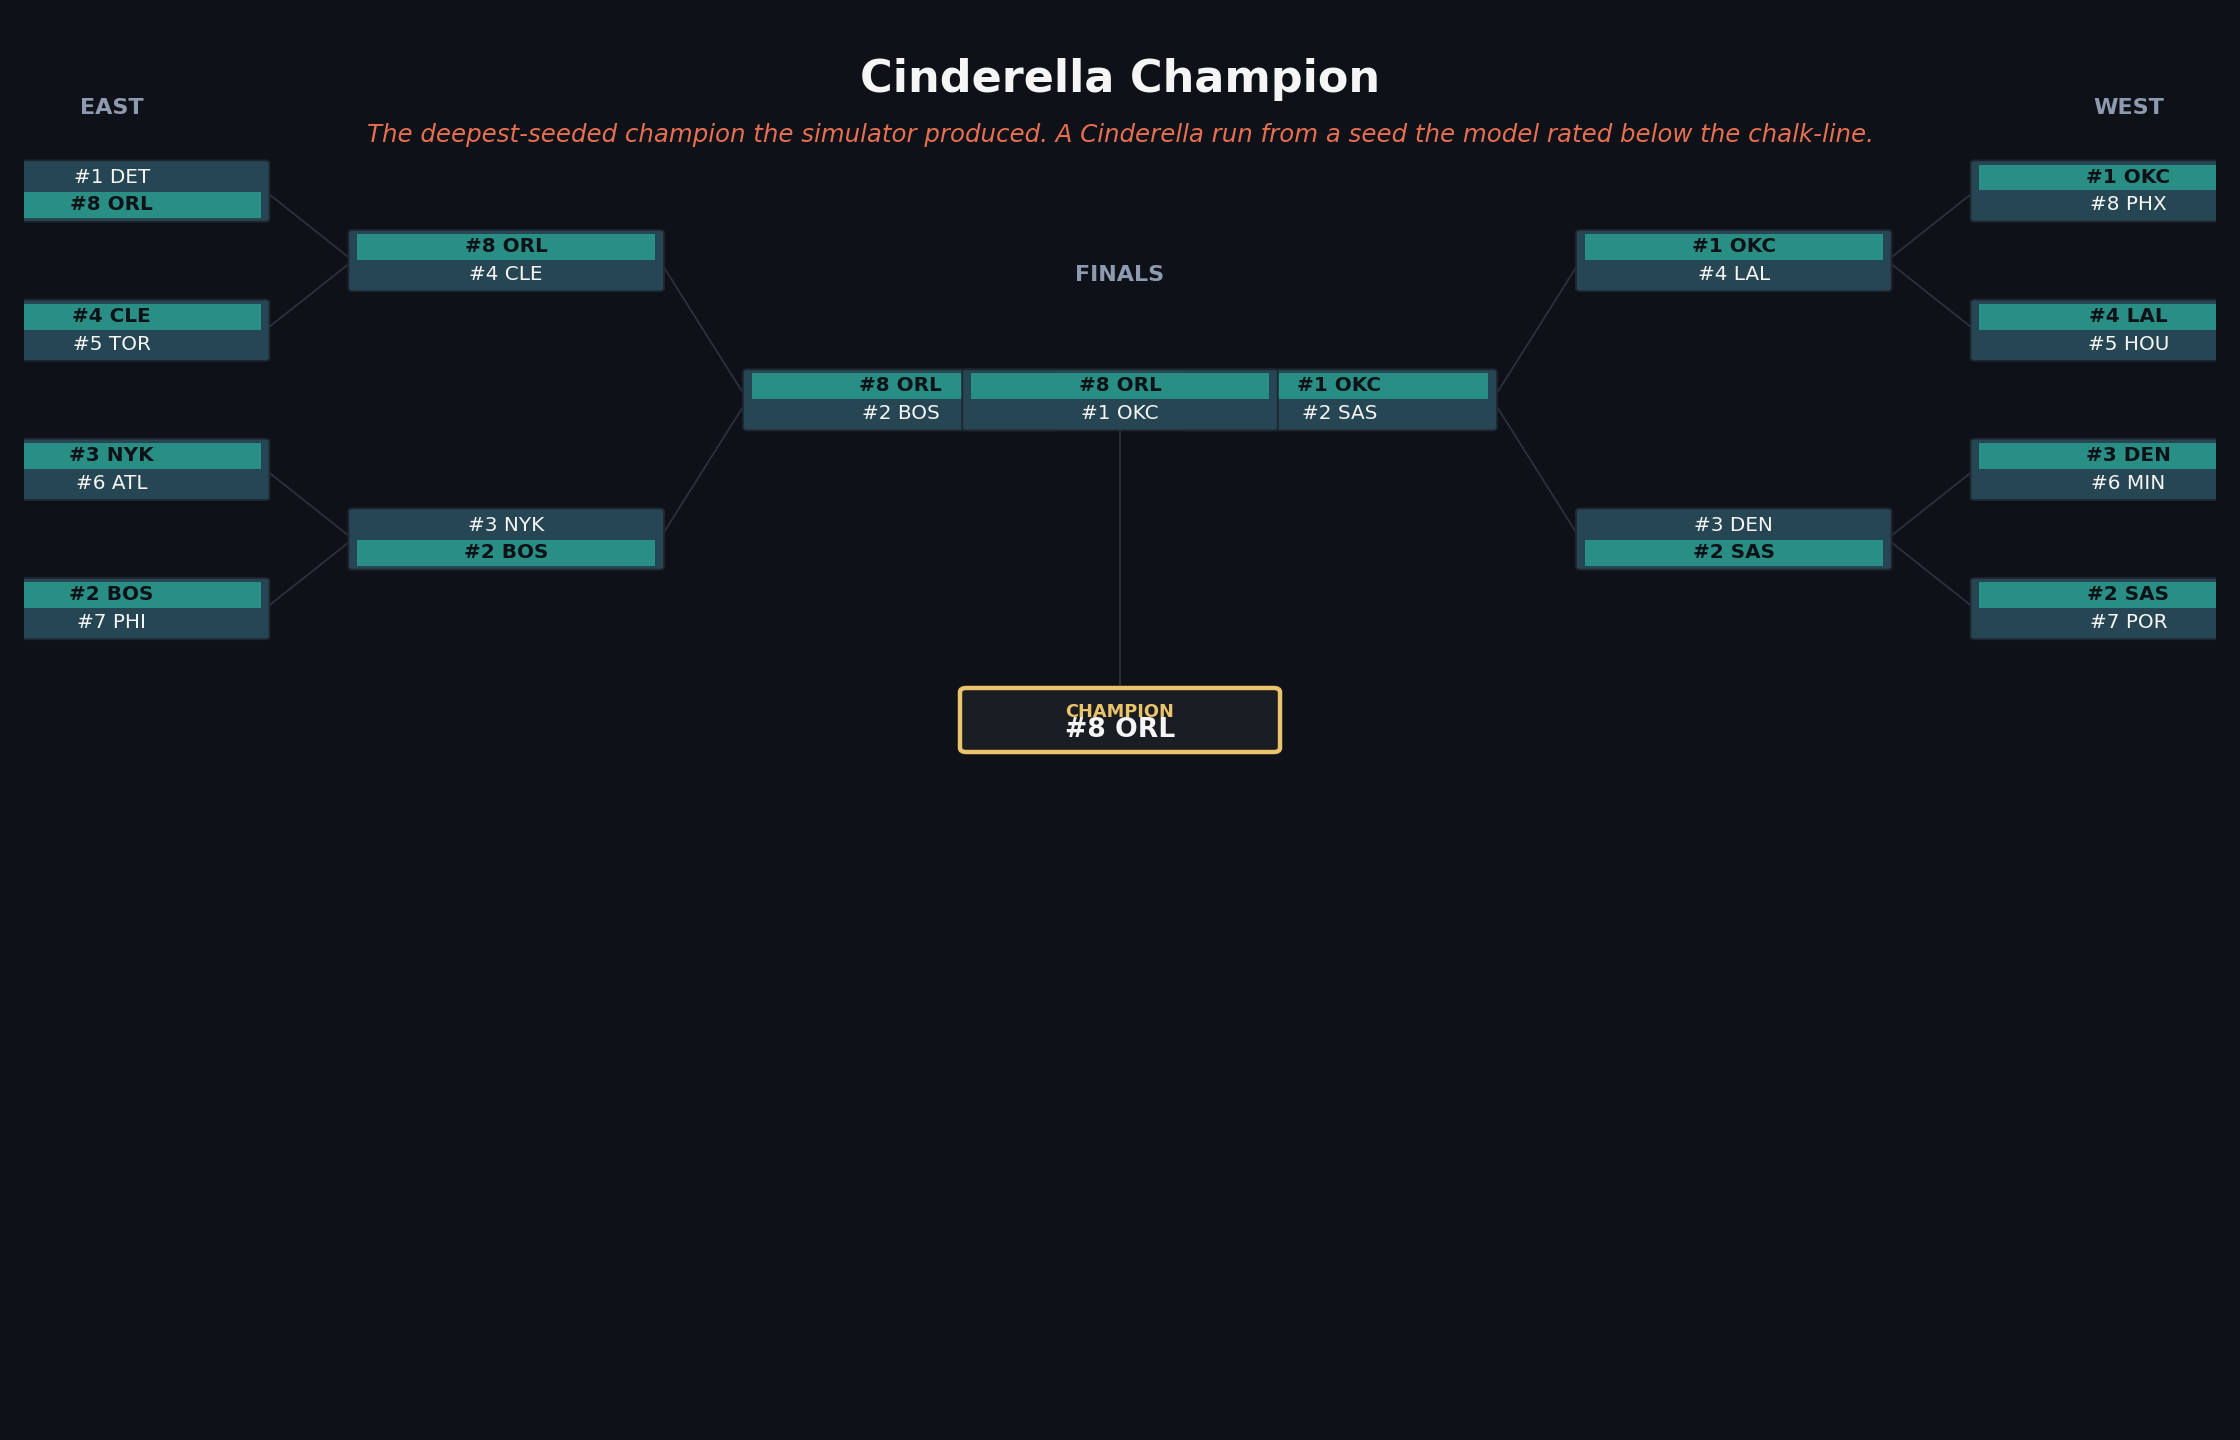
The deepest Cinderella the simulator produced is ORL — an 8-seed — over OKC. The model crowns an 8-seed about once every 500 runs (0.2%). It exists in the distribution, but it's not where you put your money.
The full whitepaper, code, and per-trial scenarios live at github.com/illyastarikov/artificial.
How It Played Out
The model's favorite was SAS — 36% to win it all, and the single bracket it would have printed. SAS is in the Finals, so the headline call is alive.
It nailed the West. SAS and OKC were its top two by a wide margin, and they are exactly the teams that met in the West Finals; the favorite, SAS, came through. Across the first two rounds it went 9 of 12 — a 75% hit rate, the three misses (Philadelphia's comeback over Boston, Minnesota over Denver, Cleveland over Detroit) all upsets the books missed too.
It missed the East. The model loved DET and BOS — 42% and 30% to reach the Finals — and pegged the teams that actually got there, NYK and CLE, at 14% and 7%. The upsets that did it, Boston and Detroit falling, are the same ones on its miss list. So of the four conference finalists, the model got the West pair and missed the East pair: two of four, not a sweep.
A 36% favorite is a favorite, not a promise, and a model can read the field well and still be wrong about which top seeds fall. But the one bracket it would have bet has SAS cutting down the nets — and SAS is one series away. Game 1 is June 3; the title is still open.
The Last Problem
AI is function fitting by optimization. The function got enormous, but the engine is the same one Arthur Samuel described in 1959. What's changed is scale, and what scale buys is generalization. A model that fits 21,742 NBA games well enough predicts the Finals to within a few percent of where the books are. A model that fits the internet well enough holds a conversation in any language about any topic.
Thankfully, the function that solves the last problem hasn't been fit yet.