Skip to content

Blog

The Lifecycle of a Code Change

AI writes most of my code now. Here's where I let it, and where I don't.

In the last year, AI has seeped its way into every part of my development process: design docs, code, tests. It automated most of the toil I never enjoyed day-to-day, fixing presubmits, linting files, refactoring old code. It also raised the ceiling on what I could get done in a day.

Everything felt different. I stopped writing the code. I started owning the decision that it was the right code. None of it came from a new tool I was handed. It came from rewiring how I work.

The process is not automated, though, and it is further from automated than the hype suggests. The human in the loop matters more than ever, and so does your taste. The code these tools write becomes your code the moment you mail it for review. Getting the human parts right is the whole game.

So here is what my workflow actually looks like now, stage by stage.

Requirements Design Development Testing Preflight Code Review Deploy Maintenance iterate

Requirements

This is one of the few areas that's primarily human driven. Driving requirements mainly entails:

  1. Identify requirements
  2. Define scope and non-goals
  3. Gather stakeholders
  4. Set success criteria
  5. Alignment and sign-off

AI can identify requirements; but based on what? AI can "identify" stakeholders, but the only "gathering" it can do is a calendar invite. AI can draft a scope line or a success metric, but it cannot feel the deadline that decides which half to cut. AI can help with alignment if you paste in the comments from your design doc; but can it distill a meeting full of conflicting opinions and make the correct judgment call?

Barring a huge change in the research landscape, we as humans will have to still write prompts and guide the agents to a desired outcome. How do you expect to know the destination if you don't know what it looks like?

So my advice here is to lean on the people around you. Get input from all the humans. Put forward multiple proposals and see what sticks. Be ready to be asked and ask yourself "Why", a lot.

Design

The thinner the context, the more generic your results will be. It's much cheaper to update the design than the implementation; there are few worse feelings than exhausting your model usage on an incorrect solution.

If there's a place I invest the best models, the largest research tasks, and the most tokens, it's this design phase. They usually have the longest prompts and the most back and forth. I really recommend going back-and-forth with the model for several iterations to make sure your architecture is clear.

I'd recommend setting up skills or MCP servers that point to your corporate corpus of information. That way existing infrastructure gets reused, company standards get met, and the model stops inventing APIs that don't exist in your codebase.

Development

Since 2025, almost all of the code I submitted at work was AI generated. I felt sneaky at first, the models weren't quite perfect, and outputs needed a lot of refinement. But the models improved, and so did my confidence in them. I knew there was something here when I kept showing my teammates the AI tooling available and they started adopting it.

If the requirements are gathered and the design is documented, most of this work will be oversight. I'll inactively monitor the agents and gently nudge them in the direction I think is right. When they're done, I read the summary of what they accomplished, and probe about the high-level details. Finally, I will manually test the new feature out to make sure it behaves as expected.

I find that the agents work best when they have a metric or goal they can loop over.

Testing

Testing has never mattered more. When you wrote every line yourself, the tests confirmed what you already believed. When an agent wrote the line, the tests are how you find out what it actually did. They are also the metric the agent loops against: hand it a failing test and a way to run it, and it will grind until the bar goes green.

Whether you write the tests first (test-driven development) or after is a matter of taste. With agents I write them first more often than I used to, because a concrete, runnable definition of done is the cleanest prompt there is.

Aim for a good mix of unit, integration, and end-to-end (e2e) tests. I target roughly 70% unit, 20% integration, and 10% e2e across the whole codebase, not per commit.

End-to-end (10%)

Integration (20%)

Unit (70%)

At work I read every line of code I ship to production. On personal projects, I mostly read the tests and trust them to catch the rest.

Preflight Checks

Everything up to here was about building the right thing. Everything from here to review is about not embarrassing yourself: the unglamorous gate between "works on my machine" and "someone else now has to read this." Three habits do most of the work.

A Proper Readover

Your code reviewer should never be the first person to read your code. It does not matter if the change is a single line; you read it first.

Read it in the same tool your reviewer will use, the diff view, not your editor. The diff is a different lens. Things that looked fine while you were writing them look wrong sitting next to everything else that changed: the debug print you forgot, the commented-out block, the variable you renamed everywhere but one place, the function that quietly grew three arguments past where it should have been split.

This matters more, not less, when an agent wrote the code. You are no longer the author who remembers every keystroke; you are the first reviewer of a change you mostly watched happen. Read it like a stranger wrote it, because in a sense one did.

The Commit

Your commit messages are an index into your work; how accurate is your index? The code tells you what the system does today. The history tells you how it got there, and why. Six months from now, staring at a line you do not remember writing, the blame trail and its messages are the only narrator you have. git bisect, code archaeology, the post-incident "why is this even here": all of it reads your messages, not your cleverness.

A good commit message says exactly what was done. A great one says why. Your dead ends, failed attempts, and wrong assumptions don't belong in the code. They belong in the message, where the next person (probably you) can find them.

My messages follow a fixed shape, wired into git through commit.template so the scaffold is always in front of me:

<type>(<scope>): <subject>
<body>
<footer>
  • type is one of feat, fix, docs, refactor, perf, test, build, ci, chore, revert.
  • subject is imperative and fits in 50 characters, no trailing period.
  • body explains what and why, wrapped at 72 columns.
  • footer carries breaking changes and issue references.

On top of that scaffold, one trailer goes into about nine of every ten messages: Tested:. To fill it, I ask:

  • How did I convince myself this change was correct?
  • What manual steps did I run? What logs can I attach as proof?
  • Is this a visual change? Should I attach screenshots or a video?
  • Did I write any throwaway scripts worth keeping?
  • What did I deliberately not test, and why was that safe?

I've even gotten into the habit of writing Tested: nope, to show I thought about it and chose to skip it.

Your future self (and your agents) will thank you.

Presubmits

You know the ones. The automated gates that run before your change is allowed anywhere near main:

  • Linters and formatters (run in check mode, so CI fails on unformatted code)
  • Static analyzers and type checkers
  • Unit and integration tests
  • Build and compile checks
  • Code-coverage thresholds
  • Security and dependency scans (SAST, vulnerable-package checks)
  • License and policy checks

Run all of them locally before you send for review, not after. The fastest review is the one where the machine has already caught everything a machine can catch, so your reviewer spends their attention on what only a human can see. Wire them into a pre-commit hook and you never have to remember.

The readover, the commit, and the presubmits live as one tickable list in The Commit Checklist.

Code Review

You did your own readover so your reviewer wouldn't have to be the first. Now they're the second, and this is where the change stops being yours alone.

A reviewer is not a linter with a pulse. The machine already caught the formatting, the dead code, the failing test. What's left is the part only another person can see: that this is the third time someone reinvented this helper, that the team agreed last month not to add config flags here, that the edge case you waved off is the one that paged them in March. They carry the context you can't, because you've been staring at this for two days and they haven't.

This is also the stage where AI quietly changed who I argue with. An agent will defend its code, cite the diff, and revise on command, but it has no standing. It can't approve the change, because approval is accountability: a second name that says this should land. When a reviewer's comment and the agent's instinct disagree, the agent doesn't get a vote. You read the comment, decide who's right, and own the call either way. Treat the thread as a conversation, not a checklist: push back when you're right, concede fast when you're not.

Deployment

Just because the code has shipped, that doesn't mean it's landed. Merged is not deployed, deployed is not in front of users, and in front of users is not the same as working.

How the change reaches production is its own discipline. Roll out behind a flag, so you can turn it off without another deploy. Ship to a canary first, a thin slice of traffic, and watch it before you widen. Stage the rollout, 1% then 10% then everyone, with a metric you are watching at each step and a threshold that triggers a rollback.

Then actually look. Have you exercised the feature in production yourself, with a real account, not just in staging? Are the dashboards and alerts that would tell you it broke wired up before you need them? What is the feedback from your users, your clients, your peers?

This is another stage where AI helps least. It will happily write the rollout config and the alert rules. It cannot tell you the latency graph looks wrong, or that a customer has gone quiet.

Maintenance

Most code spends almost none of its life being written and almost all of it being maintained. The change you are proud of today is the one someone debugs at 2am next year. Possibly you.

Maintenance is the long tail: bug reports, dependency bumps, the migration when the API you built on gets deprecated, the page at 3am when your feature meets traffic you did not predict. When it breaks, stop the bleeding first (roll back, mitigate) and understand it second (root cause, a test that would have caught it, a postmortem that blames the system and not the person).

Incident

Stop the bleeding

Root cause

Regression test

Postmortem

AI is a real help here, more than I expected. Point an agent at a stack trace, the relevant logs, and the commit that introduced the regression, and it is good at the narrow, well-scoped question: what changed, and why does it fail. The messages you wrote back in the commit stage are what make that answer possible. Your index, read back to you.

The Human Parts

The pattern repeats at every stage. The agent takes the toil: the boilerplate, the failing test, the rollout config, the first draft of almost everything. What stays with you is the judgment: whether the requirement is the right one, whether the design survives contact, whether the diff reads clean, whether the latency graph looks wrong. The tools improved every month I worked this way, and the better they got, the more what was left was the part only a person could do.

I write less code than I have in years, and I have never been more on the hook for it. When it breaks at 2am, the agent that wrote it won't be the one paged. I will.
The Commit Checklist

The unglamorous gate between "works on my machine" and "someone else has to read this."

Everything below happens before you hand the change off for review. Tick the boxes as you go; they persist when you reload the page. The reasoning behind each one is in The Lifecycle of a Code Change.

Check The Scope

Read It Yourself

Cover It With Tests

Write The Commit

Run The Presubmits Locally

Open The Review

The fastest review is the one where the machine has already caught everything a machine can. Whatever is left is for the human.

Begin a Brag Doc

Document the narrative before someone else drafts it.

NOTE 📜 This is a post about Software Engineering. All views are my own and do not represent my employer. Please review my Disclosures.

📄 Brag Doc Template The structure below, as copy-paste-ready markdown.

📋 My Brag Doc The personal version: NBA arenas, gym PRs, concerts.

When I entered tech, I assumed my manager knew everything I was working on. I gave status at weekly standups. We went deep in our one-on-ones. I figured he was keeping track.

He was, but humans don't work that way. A manager runs a 6-12 person team. They hold the big picture: the major milestones, the big PRs, the design docs that landed. The rest fades fast, and compacts with every new cycle.

This is why you should keep a brag doc. A brag doc is a running log of your impact: wins, artifacts, metrics, growth. You own it. You maintain it. It's ready when you need it.

There are plenty of other reasons have one:

  1. Memory is unreliable. Both yours and your manager's. By the time calibration happens, Q1 work has been buried under three quarters of newer fires.
  2. Promotion packets need scaffolding. You can't synthesize 12 months of work into a 500-word write-up the night before. You need raw material.
  3. Calibration is comparative. Your skip-level is in a room comparing you against four other engineers. Specificity wins.
  4. Job changes happen. The doc you keep for promotion is the same doc you grab when a recruiter pings you about a senior role.
  5. Leadership rotation. Your manager rotates. So does your skip, your director, your VP. Each new chain inherits a thin model of your work, and only you can fill it in.

Brag Evolution

Initially, I communicated my achievements once a performance cycle: through the write-up. You know the one. List five achievements from the last 12 months. Or list the projects you worked on and explain their outcomes. My manager would read it and form a judgement. This was fine, for a while.

It's hard to craft a narrative in the format of the performance review. You have to explain the high level and go into gritty details, all inside a word limit. By the time you've explained the project, you have 100 words left for the impact. By the time you've made the impact case, the section is over. You cherry-pick the wins you can summarize in two sentences, not the wins that mattered most.

Around every performance review, my manager was surprised by all I had accomplished. This is actually not a good sign. It meant my manager had a thin view of what I was doing for most of the year. I needed to change that.

Then came time for my first promotion. I had to shape two years of work into a coherent case. I pored over old performance reviews, gathered everything into one doc, and updated it for the newest wins. It was a lot of work. Hence this meme:

Late-night scramble to assemble a perf write-up

The system was unsustainable.

Then came the brag doc. Thirty minutes the last Friday of each month. A few bullets, minimum. When the next perf review came around, I copied the relevant rows into the form. When the next promotion came around, the doc was already most of the packet. The mad scramble never came back.

Philosophy

Over the years of maintaining a brag doc, I have gotten quite opinionated on them. I thought they should:

Know your audience. This document isn't for you, it's for your management chain. Imagine your manager in a review session and they need to quickly justify your contributions: you need structure and hierarchy. Or you're a senior leader reviewing this document to determine promotion: you need a story and a vision. Write your document for them, not you.

Focus on impact, not contributions. I've tried a lot this cycle, some things landed resoundingly, some things landed poorly. You don't need to omit your missteps, because this proves your work was challenging. Instead, you need to focus on your most impactful work and how you got there.

Write as you go. A doc you compile two weeks before review is fragmentary at best. The doc you maintain weekly stays grounded in real artifacts: PRs you actually shipped, meetings you actually ran, bugs you actually closed.

Quantify ruthlessly. "Improved performance" is forgettable. "Cut p99 latency from 280ms to 95ms across a rollout to 1M users" is not.

Tie work to scope. Every entry should answer: what changed, who benefited, and at what scope. Without scope, "fixed a bug" reads identical to "led a multi-team migration."

And, because we live in the AI era, one last principle:

Make it AI friendly. Maintaining the doc is grunt work. Point an AI at your raw materials and it writes most of this for you. You handle the craft, curation, and story. The AI handles the toil.

Doc Template

Owning the doc lets you control the narrative: what gets surfaced, how, and to whom. The alternative is leaving it to memory.

Goals

You've probably already set these with your manager. If you're already tracking goals elsewhere, paste them in verbatim. If not, write down what you and your manager agreed to in your last planning conversation.

Examples:

  • Lead the migration of the user-auth subsystem from Service A to Service B by Q3.
  • Onboard and ramp two new mid-level engineers to independent contribution.
  • Reduce p99 latency on the recommendation API to under 100ms.

TL;DR

Bullet points of the big landings throughout the year. Punchy, data-driven, memorable. Reads like a cross between a stats sheet and a press kit.

What metrics back up your goals? Did you conduct interviews? Host an intern? Cover a broad set of data points and go deep on a few.

Examples:

  • Shipped the auth migration on the Q3 date, zero customer-facing regressions.
  • Cut p99 from 280ms to 91ms; backed by load-test results and a week of post-rollout monitoring.
  • Authored 4 design docs, reviewed 31, mentored 2 new engineers to independent contribution.
  • Closed 47 bugs, including 3 sev-2 production incidents.

Executive Summary

The overview of your cycle, written for skim-readers. Picture an outsider or a senior leader with a few paragraphs of attention: what do they need to know?

Example:

This year I focused on three workstreams: the auth migration, latency reduction, and team growth. The auth migration shipped on time and unblocked the broader platform refactor. Latency work brought us within SLO for the first time in 18 months. I also onboarded two new engineers, and now formally mentor one of them.

Workstreams

This is the meat. For each major workstream you contributed to, write 2-4 paragraphs covering: the problem, the approach you took, the outcome, and your specific contribution. Be honest about scope. If you were one of five engineers, say so. If you led the design and three others implemented, say that.

I usually have 3-5 core workstreams per cycle. Anything fewer reads as low impact. Anything more reads as scattered.

Example:

Auth Migration. Service A had been our auth provider since 2019, but its rate-limiting story didn't scale to our new mobile clients. I led the design, partnered with the security team for review, and shipped the migration to 40% of traffic in Q2 and 100% in Q3. Net result: 12x rate-limit headroom and a 30% reduction in auth-flow complexity for downstream services.

Artifacts

Now that you laid out your case, you need data to support it. You proved the quality of your work; now it's time to prove the quantity.

Here, I post everything:

  • Documents especially design docs
  • Pull Requests not just core work, but rollbacks, bug fixes (even if the bug is in your code), any sort of code contributions
  • Tickets you've closed with highly-visible ones (i.e., high number of comments) at the top
  • Meetings such as alignment sessions, peer programming, or presentations you've done
  • Awards from your peers or your management chain

The point isn't to pad the section. Calibration discussions often pivot on a specific artifact you forgot to mention. Better to have it listed and unused than missing and decisive.

Peer Reviewers

Who did you work with? In what domains? What were their contributions? Your manager will ask all three when reading your writeup. The list isn't only so they can ask others about your work; it also helps level you. If you're level N working with N+1 and N+2 reviewers who vouch for you, that's a strong promotion signal.

This list, along with your brag doc, is one of the few levers you have during this process. So make it solid. Talk with your reviewers before the cycle; ask if they have feedback for you.

Growth

The section reviewers trust most. A self-aware gap analysis signals seniority better than any single win. Name real things; vague "I should communicate more" reads as filler.

Three sub-sections cover it:

  • What you got better at. Specific skills, with evidence.
  • What you missed or got wrong. Concrete misses, with what you'd do differently.
  • Where you want feedback. Direct questions your reviewers can answer.

Example:

What I missed. Q3 incident cluster: I under-communicated to skip-level for ~2 weeks. Course-corrected with a weekly written status; feedback positive in Q4.

Quarterly Log

The raw material that feeds everything above. One entry per quarter, accumulated monthly. Each entry is a structured set of bullets: shipped, designed, helped, incidents, decisions, quotes, lessons, metrics.

This section is the most important and the most unglamorous. The Workstreams, TL;DR, and Executive Summary all draw from it. If you maintain nothing else, maintain this. By the end of the year, you'll have a year of evidence ready to be cherry-picked.

Example slice from a Q4 entry:

- Shipped:   RFC-217 reached 100% rollout
- Decisions: Deferred Project Zeta to H1 (~6 eng-weeks)
- Metrics:   p99 checkout 312ms → 297ms (post-canary)

Your Own Brag Doc

This inspired me to publish my own brag doc, of sorts. I took the things I'd done outside of work: every NBA arena I've visited, every concert I attended, every gym PR. Same idea as the work brag doc, just for the parts of life that don't have a perf review.

You can read mine here.

Whichever version you keep, personal or work or both, start it today. Open a doc, paste in three things you did this week, and don't stop. The version you'll have in 6 months is the one you'll wish you had today. Write it once a month, cash it once a year.

Brag Doc Template

A simple template for tracking your engineering impact across a performance cycle.

Copy this file, fill in your own content. Update the Quarterly logs once a month. Promote items into the upper sections every 2-4 weeks. At review time, you trim and reorder. Don't write from scratch.


Metadata

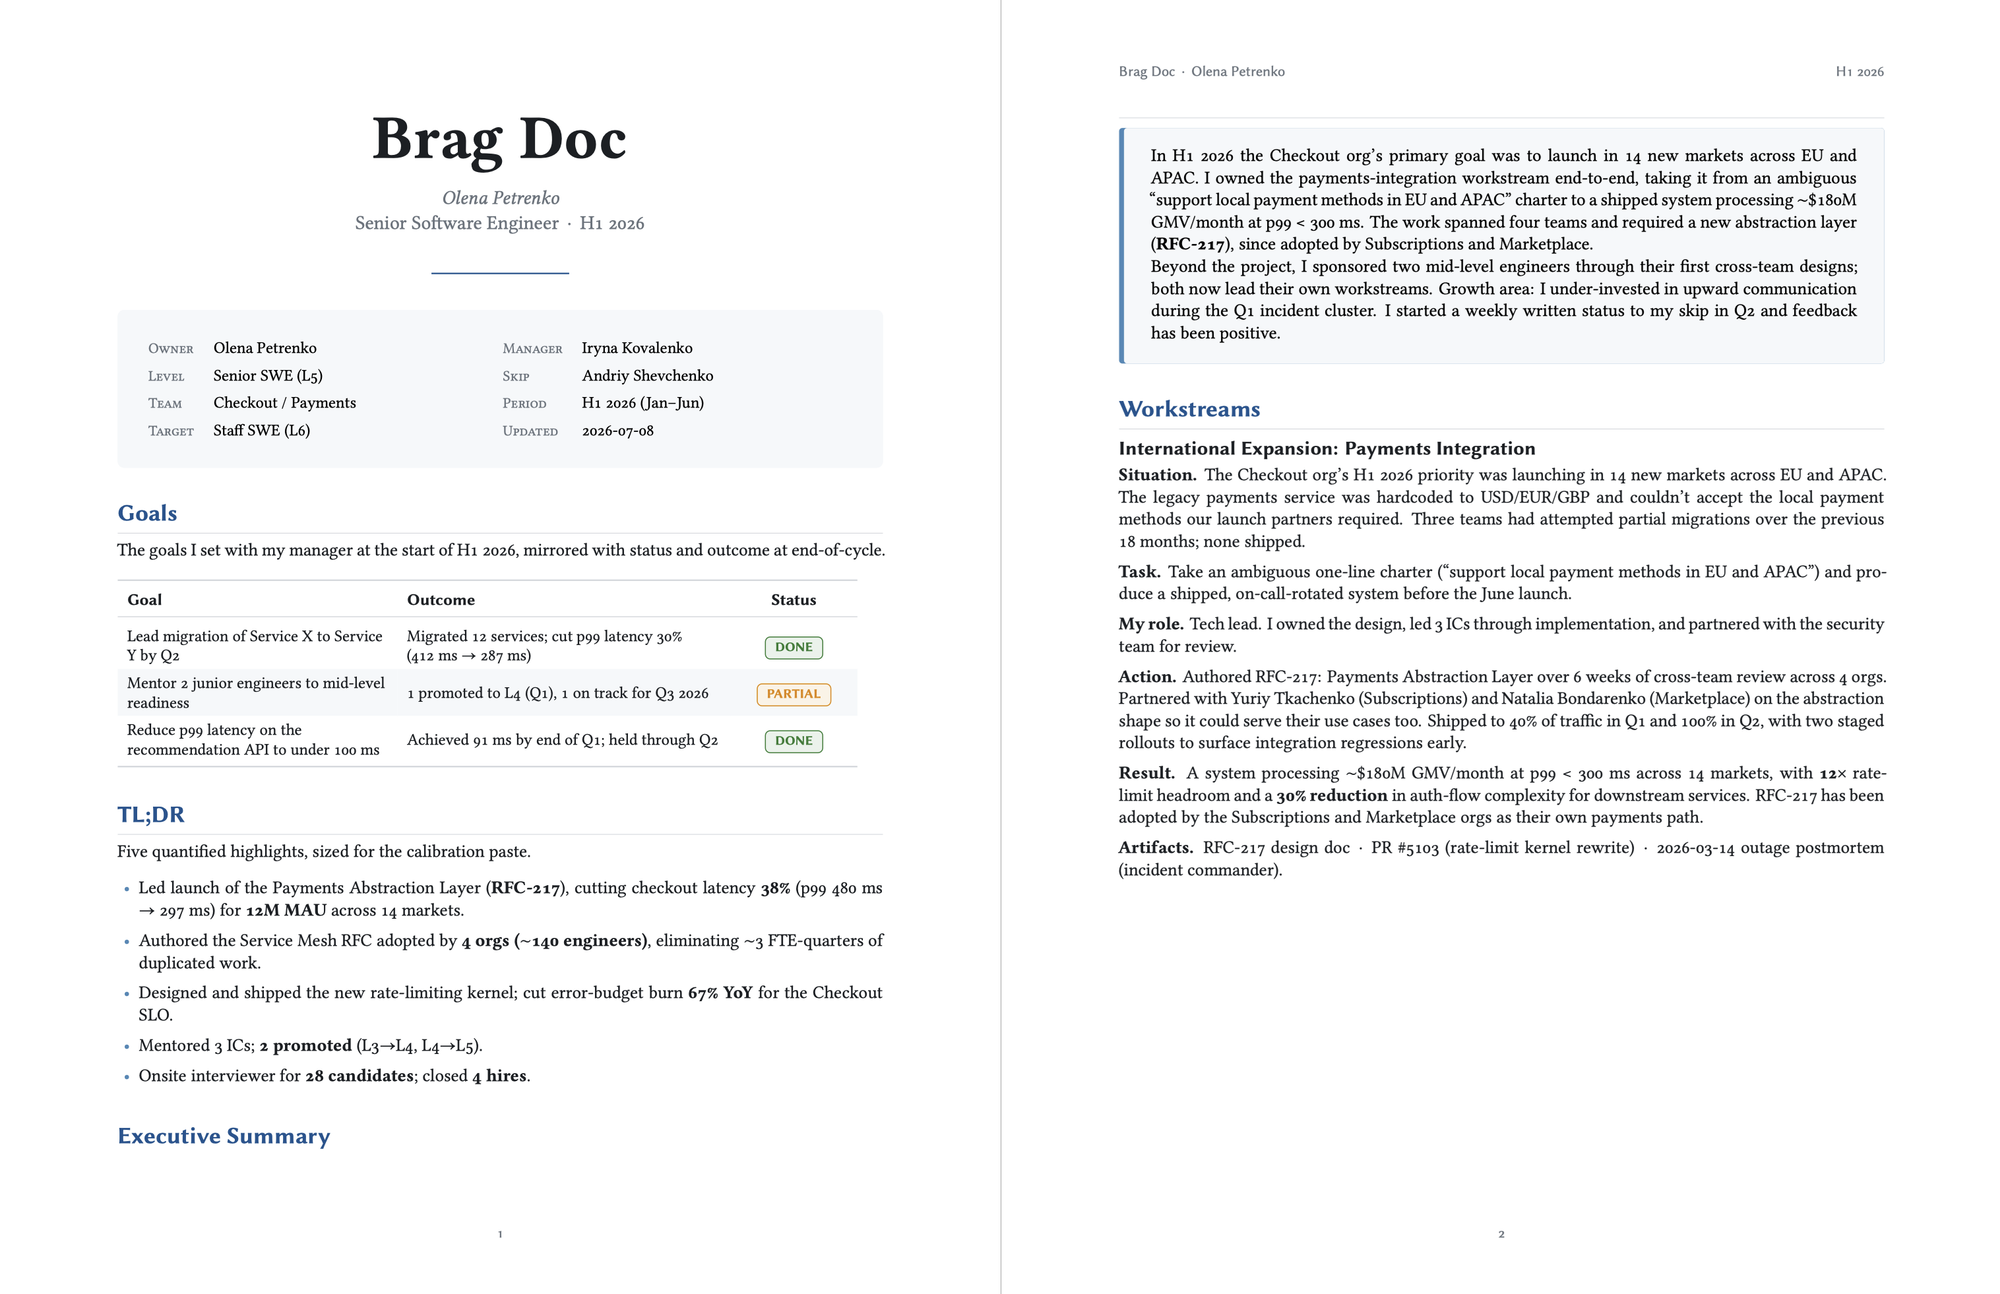
Field Value
Owner Your name
Level e.g., Senior SWE (L5)
Period e.g., H2 2025
Manager Name
Last updated YYYY-MM-DD

Goals

The 2-5 goals you set with your manager at the start of the cycle. Mirror them at the end with a status and one-line outcome.

Goal Status Outcome
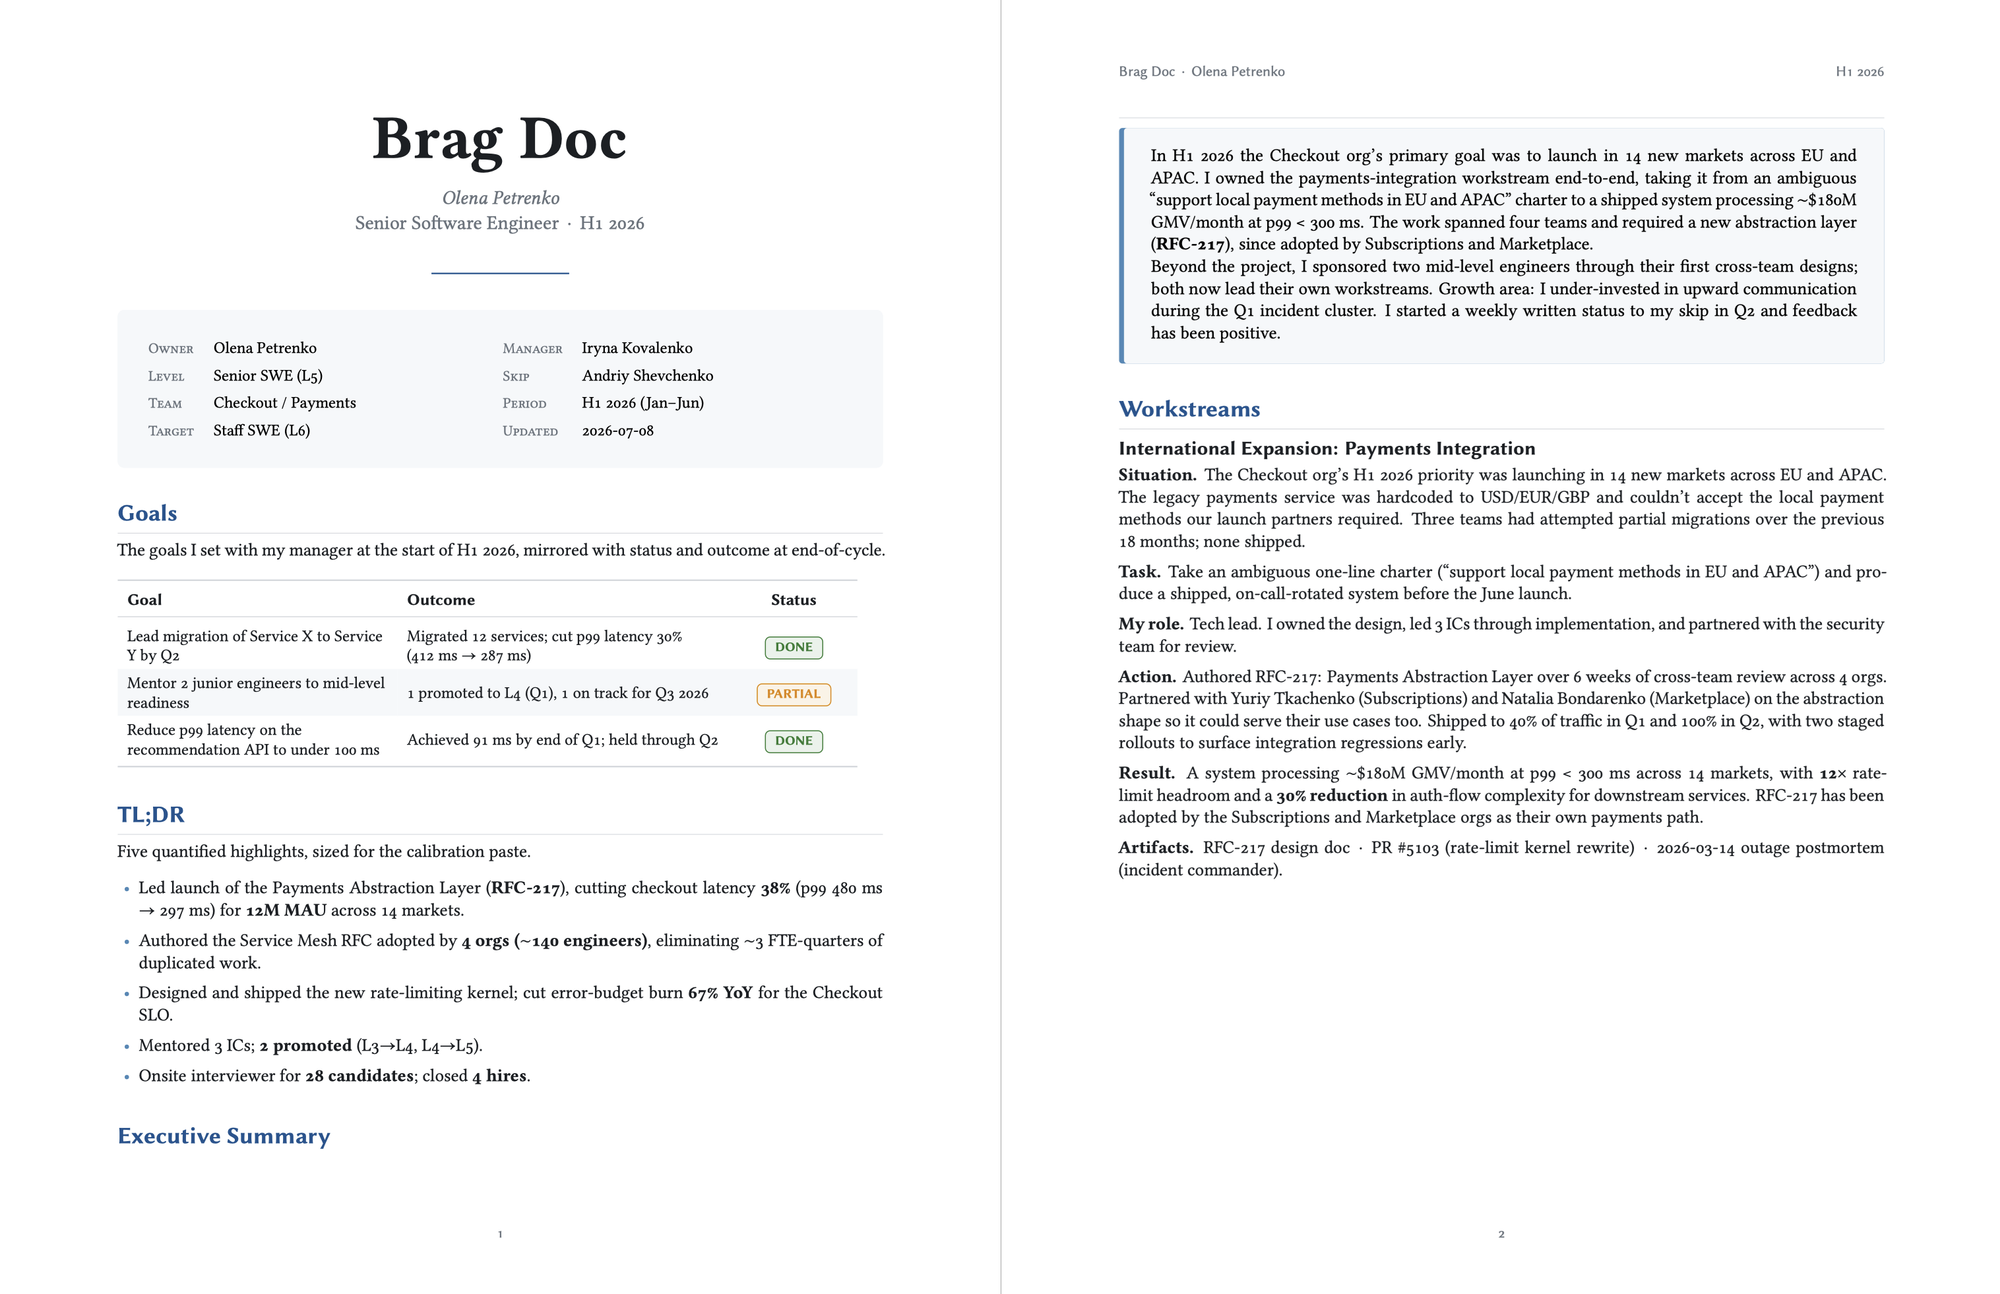
Lead the migration of Service X to Service Y by Q3 🟢 Done Migrated 12 services; cut p99 latency 30%
Mentor 2 junior engineers to mid-level readiness 🟡 Partial 1 promoted, 1 in progress

🟢 done · 🟡 partial · 🔴 missed · ⚪️ deprioritized


TL;DR

3-7 bullets, each one quantified. Lead with the biggest thing. This is what your manager pastes into calibration.

  • Led launch of, cutting checkout latency 38% (p99 480ms → 297ms) for 12M MAU.
  • Authored the Service Mesh RFC adopted by 4 orgs (~140 engineers), eliminating ~3 FTE-quarters of duplicated work.
  • Designed and shipped the new rate-limiting kernel; cut error budget burn 67% YoY.
  • Mentored 3 ICs; 2 promoted (L3→L4, L4→L5).
  • Onsite interviewer for 28 candidates; closed 4 hires.

Executive Summary

One to three short paragraphs. What was the team trying to do, what was your role in it, what's different because you were there.

In H2 2025 the Checkout org's primary goal was to launch in 14 new markets. I owned the payments-integration workstream end-to-end, taking it from an ambiguous "support local payment methods in EU and APAC" charter to a shipped system processing ~$180M GMV/month at p99 < 300ms. The work spanned four teams and required a new abstraction layer (RFC-217), since adopted by Subscriptions and Marketplace.

Beyond the project, I sponsored two mid-level engineers through their first cross-team designs; both now lead their own workstreams. Growth area: I under-invested in upward communication during the Q3 incident cluster. I've started a weekly written status to my skip in Q4 and feedback has been positive.

Workstreams

One subsection per major project. Use STAR: Situation, Task, Action, Result. 3-5 per cycle is typical. Fewer reads as low impact. More reads as scattered.

[Outcome-shaped title, e.g., "Made international expansion possible"]

  • Situation. What problem existed before you started? Quantify the pain.
  • Task. What you were asked, or what you decided, to do.
  • My role. Sole engineer / TL with 4 ICs / co-lead with @alice / reviewer & sponsor of @bob's work. Honest attribution makes your real contribution legible.
  • Action. 3-6 things you did. Decisions you made and why. Trade-offs you owned. Partners (PM, design, data) you worked with.
  • Result. Numbers. Adoption. Behavior change.
  • Artifacts. Links to design docs, PRs, launches, dashboards, postmortems.

Repeat the block above for each major workstream.


Artifacts

Direct links. Reviewers cross-reference these. Keep it skim-able.

  • Design docs / RFCs. Title: one line on impact
  • Significant PRs. Title: one line on impact
  • Talks / posts. Title: venue, audience size
  • Incidents / on-call. e.g., IC for 3 sev-2s; 8 shifts; ~24 pages
  • Hiring. Loops: 28 · Hires closed: 4 · Bar-raiser: 12
  • Above and beyond. Open-source, internal community work, DEI, conference talks

Peer Reviewers

Who can speak to which work. Share this section with them so they know what to comment on.

Reviewer Relationship What they can speak to
@alice Cross-team peer RFC-217 review, payments collab
@bob Direct mentee Mentorship effectiveness
@carol Sister-team TL Cross-team alignment, incident response

Growth

The section reviewers trust most. Name real things. "I should communicate more" is not a growth area.

What I got better at. e.g., Writing strategy docs that get traction outside my org. 0 → 3 adopted RFCs.

What I missed or got wrong. e.g., Q3 incident cluster: I under-communicated to skip-level for ~2 weeks. Course-corrected with a weekly written status; feedback positive in Q4.

Where I want feedback. e.g., Am I operating at the L6 bar on technical scope? Where am I still acting like a Senior IC instead of a Staff IC?


Quarterly Log

The raw material. Update once a month; one entry per quarter. Promote items upward every 2-4 weeks.

Template entry

## YYYY Qn

- Shipped:   [Major PRs, launches, decisions this quarter]
- Designed:  [RFCs, docs, proposals]
- Helped:    [Mentees, unblocks, sponsored work]
- Incidents: [On-call shifts, sev levels, what I learned]
- Decisions: [Strategic decisions that landed]
- Quotes:    [Positive feedback received this quarter]
- Lessons:   [Honest notes; private to you]
- Metrics:   [Dashboard movement traceable to me]

Example entry

## 2025 Q4

- Shipped:   RFC-217 (payments abstraction) reached 100% rollout
             Rate-limit kernel to 100% (canary started Q3)
             Onboarded @marketplace onto the new auth flow
- Designed:  RFC-217 v3 published; reviews from 4 orgs
             RFC-218 (Service Mesh follow-on) draft circulated
- Helped:    Co-authored @alice's L3 → L4 promo packet
             Sponsored @bob's first cross-team design review
             Unblocked @marketplace on auth migration (3 × 40min)
- Incidents: IC for 2 sev-2s (Oct 14, Nov 2); 12 pages total
             Cut false-positive rate 60% via alert config
- Decisions: Deferred Project Zeta to H1 (~6 eng-weeks saved)
             Pushed back on premature dual-write; saved a quarter
- Quotes:    @director on RFC-217: "clearest doc this quarter"
             @skip on RFC-218: "exactly the right altitude"
- Lessons:   4-day meeting series that should've been a doc;
             next time, propose async first
- Metrics:   p99 checkout 312ms → 297ms (post-canary)
             Build time 41min → 17min (CI parallelization)
             Error budget burn 4.2× SLO → 1.4× SLO YoY

The Vanishing Keystrokes Bug

How a faceless background agent ate my typing, and the script that caught it.

A few days into an uptime, deep in something, my Mac would stop listening. Not a crash, not a freeze. The cursor still moved, windows still highlighted under it, I could click anything. But the keyboard went dead: I'd type a whole sentence into a window that looked focused and watch zero characters land. Clicking didn't help. Sometimes it cleared after a few seconds; sometimes I rebooted and bought another day or two of quiet.

A bug that only shows up after hours of uptime, never on a cold boot, and clears on reboot is the worst kind. You can't reproduce it on demand, so you can't poke at it. I finally cornered it, and the culprit wasn't what I assumed.

The Symptoms

If your Mac does this too, start here. The shape of the failure tells you where to look.

  • The mouse works. The keyboard doesn't. Pointer moves, clicks land, but no window accepts text.
  • It's system-wide, not one app. Every window is dead, whichever one you click into.
  • It builds up over uptime. Fine on a fresh boot, more frequent the longer the machine stays awake.
  • A reboot fixes it. Temporarily. It always comes back.
  • The focused window looks slightly de-focused, title bar greyed out, as if nothing is frontmost.

That combination rules a lot out. It isn't a hardware keyboard fault: the mouse and keyboard share enough of the input stack that a real HID failure takes both. It isn't one misbehaving app. It points at the part of the OS that decides where keystrokes go, and at something that corrupts that decision the longer you stay logged in.

Two Kinds of "Front"

macOS tracks "in front" in two places that are supposed to agree.

  1. The active application (LaunchServices and NSWorkspace). Apple defines frontmostApplication bluntly: the app that receives key events. lsappinfo reports it.
  2. The key window (WindowServer). Within the active app, keys flow to the key window, then to its first responder, the text field your cursor sits in. No window that can become key means no key window, and nowhere for text to land.

A third notion, Accessibility's AXFrontmost (what AppleScript's System Events reports), tracks the app whose UI is actually up front.

On a healthy Mac all three agree and you never think about it. The bug lives in the gap: if LaunchServices says one app is active while Accessibility says another, the OS routes your keystrokes to an app you aren't looking at. If that app has no window, they evaporate.

Bug Catcher

Check both notions from the terminal, especially while the bug is happening:

# LaunchServices: who owns key events?
lsappinfo info -only name "$(lsappinfo front)"

# Accessibility: who's actually up front?
osascript <<'EOF'
tell application "System Events"
  name of first application process whose frontmost is true
end tell
EOF

Healthy, these match. Mine didn't:

LaunchServices : "Logitech G HUB Agent"
Accessibility  : wezterm-gui

LaunchServices thought a faceless agent, the Logitech G HUB Agent, was the active app receiving key events, while the app I was clicking into was my terminal. My keystrokes were routing to an agent with no window.

Two commands catch it if your timing is lucky. The bug is intermittent, so I wrote a monitor that shouts the moment the two disagree.

focus-spy

It polls both notions once a second, logs every change, and flags MISMATCH when the PIDs differ. Drop it in your $PATH, chmod +x it, run it.

#!/usr/bin/env bash
# focus-spy - find out what's stealing keyboard focus on macOS.
#
# macOS tracks "the frontmost app" in two places that should agree:
#   * LaunchServices / NSWorkspace - the app that RECEIVES KEY EVENTS
#       (what `lsappinfo front` reports)
#   * Accessibility (AXFrontmost)  - the app whose UI is up front
#       (what System Events reports)
# When a background agent shoves itself into the first one without a
# real window, the two disagree, and your keystrokes fall in the gap.
# This logs both once a second and shouts when their PIDs differ.
#
# Usage:
#   focus-spy             # watch (Ctrl-C to stop)
#   focus-spy mark NOTE   # mark the instant typing dies
#   focus-spy report      # print the timeline, sorted

set -uo pipefail
LOG="${FOCUS_SPY_LOG:-$HOME/.local/state/focus-spy.log}"
mkdir -p "$(dirname "$LOG")"

ts() { date '+%Y-%m-%d %H:%M:%S'; }

# LaunchServices' frontmost (the key-event owner) as "name#pid".
# Compare by PID, not name: the two APIs spell the same app
# differently ("WezTerm" vs "wezterm-gui"); only the PID is identity.
ls_front() {
  local asn name pid
  asn="$(lsappinfo front 2>/dev/null)"
  name="$(lsappinfo info -only name "$asn" 2>/dev/null)"
  name="${name#*=}"; name="${name//\"/}"
  pid="$(lsappinfo info -only pid "$asn" 2>/dev/null)"
  pid="${pid##*=}"
  printf '%s\n' "${name:-?}#${pid:-?}"
}

# Accessibility's frontmost (the visible app) as "name#pid". First run
# may prompt your terminal for Automation access to System Events.
ax_front() {
  osascript 2>/dev/null <<'OSA'
tell application "System Events"
  set p to first application process whose frontmost is true
  return (name of p) & "#" & (unix id of p)
end tell
OSA
}

watch() {
  echo "focus-spy: watching (Ctrl-C to stop). Log: $LOG"
  local prev="" ls ax line tag
  while :; do
    ls="$(ls_front)"; ax="$(ax_front)"
    line="ls=[$ls]  ax=[$ax]"
    if [[ "$line" != "$prev" ]]; then
      [[ "${ls##*#}" == "${ax##*#}" ]] && tag="ok      " || tag="MISMATCH"
      printf '%s\n' "$(ts)  $tag  $line" | tee -a "$LOG"
      prev="$line"
    fi
    sleep 1
  done
}

case "${1:-watch}" in
  watch)  watch ;;
  mark)   shift
          printf '%s\n' "$(ts)  MARK      >>> ${*:-typing died} <<<" \
            | tee -a "$LOG" ;;
  report) sort "$LOG" 2>/dev/null || echo "no log yet" ;;
  *)      echo "usage: focus-spy [watch|mark NOTE|report]"; exit 1 ;;
esac

Leave focus-spy watch running in a spare terminal. The instant the keyboard dies, run focus-spy mark "typing died" in any shell, then focus-spy report. Look for a MISMATCH line: whatever sits on the ls= side is your thief. Every one of mine read ls=[Logitech G HUB Agent].

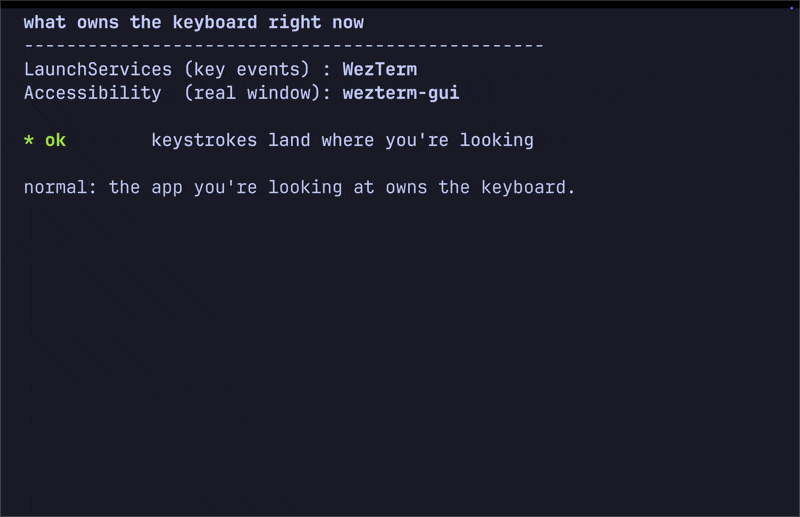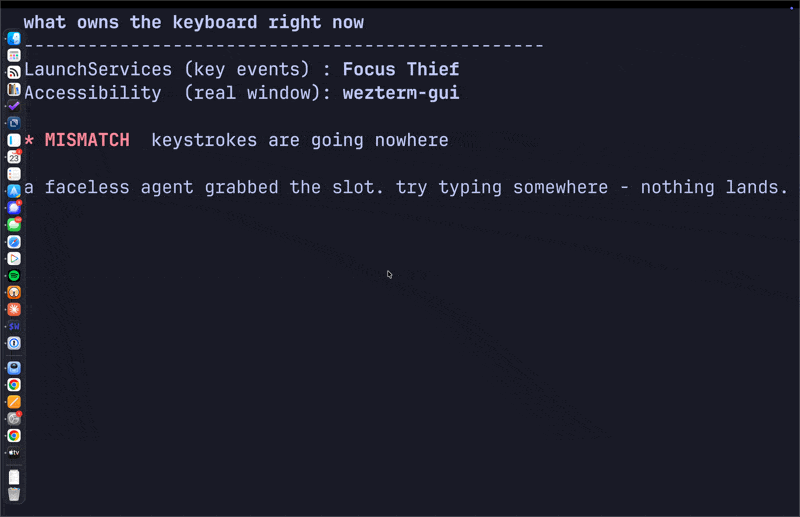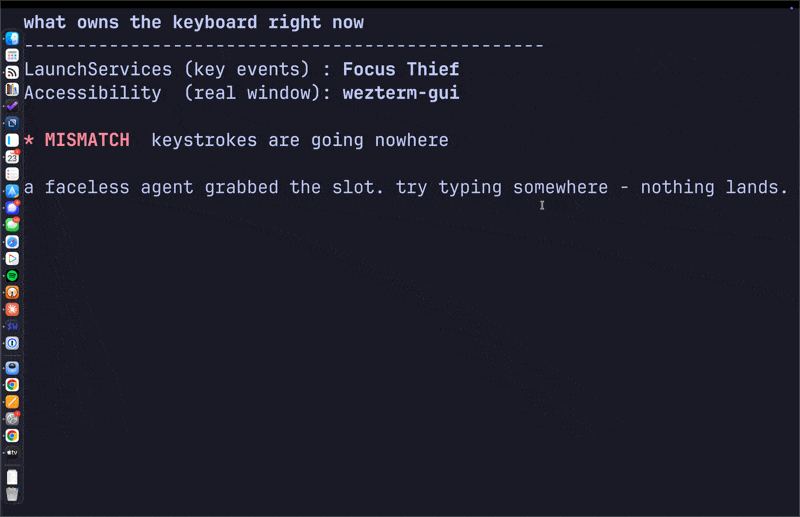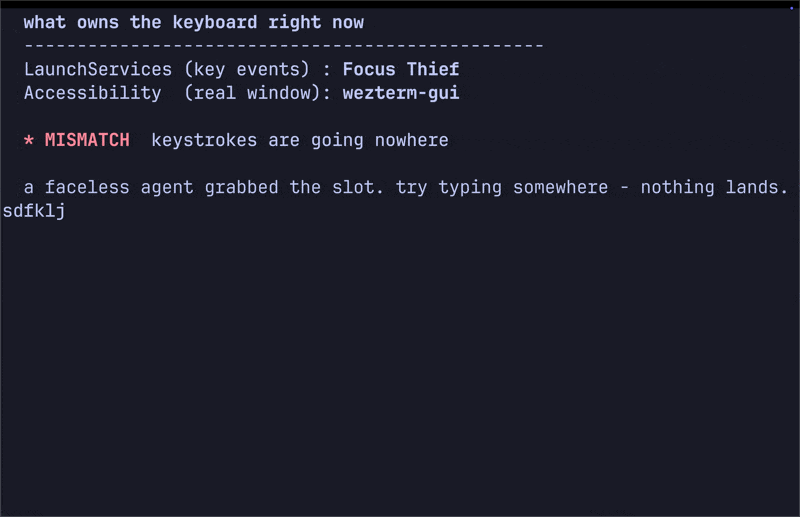
Terminal status flipping from ok to MISMATCH and back as a faceless agent seizes the keyboard

The two fronts diverging on demand. A faceless stand-in agent (built to reproduce the bug) seizes the LaunchServices slot while the terminal keeps Accessibility focus, so the status flips to MISMATCH, then back the instant it exits.

The Smoking Gun

A monitor tells you who; a kill test tells you whether you're right. The LaunchServices front process read Logitech G HUB Agent more than twenty samples in a row. So I killed the stack and watched it the instant it died:

killall lghub_agent lghub_system_tray lghub
lsappinfo info -only name "$(lsappinfo front)"

The active app snapped back to WezTerm and held. Both notions agreed. Typing was solid. G HUB's agent had been parking itself in the active-app slot and never letting go.

Why It Breaks

The active app receives key events, routed to its key window's first responder. An agent app (LSUIElement, no Dock icon) can still become the active app, and the old SetFrontProcess API was deprecated for NSRunningApplication.activate, which developers have long reported is easy to leave in an inconsistent state. G HUB falls into exactly that: it activates itself, probably an unbalanced activate on a device-poll loop, and becomes the active app without a window that can become key. The keyboard now points at a process with no first responder, so keystrokes are dropped, not stolen, just discarded, until you click into a real app. The mouse still works because mouse events are hit-tested by pointer location, not by which app is active. (Don't confuse it with Secure Input, where an app legitimately swallows every keystroke and forgets to stop; there both notions of "front" still agree. The mismatch is the tell.)

You're not imagining it, either. Another engineer built the same kind of monitor and clocked G Hub grabbing focus 47 times in four minutes. A MacRumors thread nails it: G Hub "keeps trying to get focus ... since it only runs in the background and has no window to receive the focus, the frontmost app of the system loses focus." Logi Options+ does the same. The trigger looks like wake and device re-enumeration, which fits why it snowballs over uptime and resets on reboot. The lesson: when you finally name a weird bug, search the name. You're rarely the first to hit a real defect.

The Fix

Right now, quit it:

killall lghub_agent lghub_system_tray lghub

Permanently: a launch agent restarts it at login (/Library/LaunchAgents/com.logi.ghub.plist, RunAtLoad). Move it aside, reversible:

sudo mv /Library/LaunchAgents/com.logi.ghub.plist \
  ~/Documents/backup/com.logi.ghub.plist

Then check System Settings, General, Login Items & Extensions for any Logitech entry. If you don't use Logitech G gaming gear, uninstall G HUB outright; Logi Options+ already covers a normal mouse.

My Mac types again. Now when focus feels off, I reach for focus-spy watch in a corner terminal, because the next thief trips the same wire.